
Let me say something that might upset some people.
Most SEO tools are just API calls with a pretty UI on top.
Ahrefs. Semrush. Moz. DataForSEO. They’re all doing the same thing you can do — querying search engines, parsing structured data, tracking rank positions over time. They just wrap it in a dashboard and charge you $100–$500/month for the privilege.
If you’re a developer, you have a better option.
You can build your own SEO tool — one that does exactly what you need, nothing you don’t, costs less than $5/month to run at real scale, and teaches you more about how search actually works than any tutorial ever could.
This is that tutorial.
We’re going to build a functional SEO competitor spy tool using three APIs:
- Serpent API — live SERP data (Google, Bing, and 3 others)
- DataForSEO Backlinks API — Real-Time Backlinks API
- Serpent API News endpoint — real-time news monitoring for brand mentions
- Serpent API AI Rank endpoint — check if Gemini/ChatGPT/Perplexity cite your domain
By the end, you’ll have a Python script that:
- Tracks your keyword rankings daily
- Monitors what your competitors rank for (that you don’t)
- Catches brand mentions in the news before your marketing team does
- Checks if AI search engines are citing your site
Let’s build.
Why Build Instead of Buy?
Before we write a line of code, let me make the financial case — because it’s embarrassing.
For 2,000 keywords tracked daily, a well-known rank tracker charges ~$224/month. That’s 60,000 API calls a month. At Serpent API’s Scale tier ($0.03/1K calls), the same 60,000 calls costs $1.80/month.
That’s not a discount. That’s 124× cheaper. And you own the data, you control the schema, and you’re not locked into someone else’s feature roadmap.
The one-time cost to get to the Scale tier is a $500 deposit — which doesn’t expire, never downgrades, and is credited to your usage. You’d recoup it in a month vs. any mid-tier SEO subscription.
Free tier: 10 calls, no card. That’s enough to get through this entire tutorial.
What We’re Building
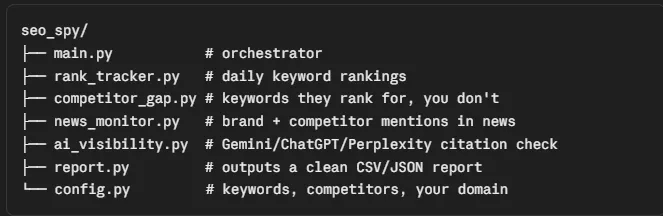
Simple. Flat. No framework overhead.
Setup
pip install requests python-dotenv# .env
SERPENT_API_KEY=your_key_here# config.py
MY_DOMAIN = "yourdomain.com"
KEYWORDS = [
"serp api",
"rank tracking api",
"google search api",
"news monitoring api",
"local rank tracking",
]
COMPETITORS = [
"serpapi.com",
"dataforseo.com",
"serper.dev",
]
COUNTRY = "us"
LANGUAGE = "en"Get your free API key at Serpent API — no card required.
Part 1: Rank Tracker
The foundation. For each keyword, we call the SERP API, scan the organic results, and note our position.
# rank_tracker.py
import requests
import os
from config import MY_DOMAIN, KEYWORDS, COUNTRY

API_KEY = os.getenv("SERPENT_API_KEY")
BASE_URL = "https://apiserpent.com/api/search/quick"


def snap_to_ten(n, cap=100):
    """
    Serpent API bills per started block of 10.
    Requesting 11 results costs the same as 20.
    Always snap to the nearest 10 to avoid paying for empty slots.
    """
    return min(cap, ((n + 9) // 10) * 10)


def check_rank(keyword, target_domain, num_results=100):
    """
    Returns the organic rank position (1-indexed) for target_domain
    on the given keyword. Returns None if not in top results.
    """
    response = requests.get(
        BASE_URL,
        params={
            "q": keyword,
            "engine": "google",
            "num": snap_to_ten(num_results),
            "country": COUNTRY,
            "gl": COUNTRY,
        },
        headers={"X-API-Key": API_KEY},
        timeout=30,
    )
    response.raise_for_status()
    data = response.json()

    for result in data.get("results", []):
        if target_domain in result.get("url", ""):
            return {
                "keyword": keyword,
                "position": result["position"],
                "url": result["url"],
                "title": result.get("title", ""),
            }

    return {
        "keyword": keyword,
        "position": None,
        "url": None,
        "title": None,
    }


def run_rank_check():
    print("🔍 Checking keyword rankings...")
    results = []
    for keyword in KEYWORDS:
        result = check_rank(keyword, MY_DOMAIN)
        rank_display = result["position"] if result["position"] else "not found"
        print(f"  '{keyword}' → position {rank_display}")
        results.append(result)
    return results
Run it once and you’ve got a baseline. Run it daily (cron job or GitHub Action) and you’ve got a rank tracker.
Part 2: Competitor Gap Analysis
This is where it gets interesting.
We’re going to check what your competitors rank for on your target keywords — and find the ones where they’re in the top 10 while you’re not. That’s your hit list.
# competitor_gap.py
import requests
import os
from config import KEYWORDS, COMPETITORS, MY_DOMAIN, COUNTRY

API_KEY = os.getenv("SERPENT_API_KEY")
BASE_URL = "https://apiserpent.com/api/search/quick"


def get_serp_positions(keyword, domains, num_results=100):
    """
    For a keyword, return the rank position of each domain.
    Returns dict: {domain: position_or_None}
    """
    response = requests.get(
        BASE_URL,
        params={
            "q": keyword,
            "engine": "google",
            "num": num_results,
            "country": COUNTRY,
        },
        headers={"X-API-Key": API_KEY},
        timeout=30,
    )
    response.raise_for_status()
    data = response.json()

    positions = {domain: None for domain in domains}

    for result in data.get("results", []):
        url = result.get("url", "")
        for domain in domains:
            if domain in url and positions[domain] is None:
                positions[domain] = result["position"]

    return positions


def find_gaps():
    """
    Find keywords where competitors rank top-10 but you don't.
    These are your priority content opportunities.
    """
    print("🕵️  Running competitor gap analysis...")
    gaps = []
    all_domains = [MY_DOMAIN] + COMPETITORS

    for keyword in KEYWORDS:
        positions = get_serp_positions(keyword, all_domains)

        my_position = positions[MY_DOMAIN]
        competitor_positions = {
            d: p for d, p in positions.items()
            if d != MY_DOMAIN and p is not None and p <= 10
        }

        # Gap = competitors ranking top 10, you are not
        if competitor_positions and (my_position is None or my_position > 10):
            gap = {
                "keyword": keyword,
                "my_position": my_position or "not ranked",
                "competitors_ranking": competitor_positions,
            }
            gaps.append(gap)
            print(f"  ⚠️  GAP: '{keyword}' — you: {gap['my_position']} | "
                  f"competitors: {competitor_positions}")

    print(f"\n  Found {len(gaps)} keyword gaps.")
    return gaps
This is the “spying” part — and it’s completely above board. All you’re doing is reading the same public search results any user sees. You’re just doing it programmatically and at scale.
The output of this function is a prioritized content calendar. Every gap is a page you need to write.
Part 3: News Monitor
This one is underrated.
If a competitor gets a press mention, a product review, or a Reddit thread blowing up — and you find out three days later — you missed the window to respond, piggyback, or write a counter-piece that captures the same search intent.
We’re going to check the news every morning.
# news_monitor.py
import requests
import os
from datetime import datetime, timedelta
from config import MY_DOMAIN, COMPETITORS

API_KEY = os.getenv("SERPENT_API_KEY")
NEWS_URL = "https://apiserpent.com/api/news/search"


def search_news(query, freshness="day"):
    """
    freshness options: "hour", "day", "week", "month"
    Returns list of news articles matching the query.
    """
    response = requests.get(
        NEWS_URL,
        params={
            "q": query,
            "freshness": freshness,
            "engine": "google",
            "num": 25,
        },
        headers={"X-API-Key": API_KEY},
        timeout=30,
    )
    response.raise_for_status()
    return response.json().get("articles", [])


def monitor_brand_and_competitors():
    """
    Check news mentions for your brand + each competitor.
    """
    print("📰 Running news monitor...")
    report = {}

    # Your brand mentions
    your_brand = MY_DOMAIN.replace(".com", "").replace(".io", "")
    articles = search_news(your_brand, freshness="day")
    report[MY_DOMAIN] = articles
    print(f"  {MY_DOMAIN}: {len(articles)} mentions in last 24h")

    # Competitor mentions
    for competitor in COMPETITORS:
        brand = competitor.replace(".com", "").replace(".io", "")
        articles = search_news(brand, freshness="day")
        report[competitor] = articles
        print(f"  {competitor}: {len(articles)} mentions in last 24h")

    return report


def find_competitor_coverage_gaps(news_report):
    """
    Find stories where competitors got coverage but you didn't.
    These are PR opportunities you missed — or can still respond to.
    """
    your_articles = set(
        a.get("url", "") for a in news_report.get(MY_DOMAIN, [])
    )

    gaps = []
    for competitor, articles in news_report.items():
        if competitor == MY_DOMAIN:
            continue
        for article in articles:
            if article.get("url") not in your_articles:
                gaps.append({
                    "competitor": competitor,
                    "title": article.get("title"),
                    "url": article.get("url"),
                    "source": article.get("source"),
                    "published": article.get("published_date"),
                })

    return gaps
At $0.01/1K calls, running this daily for an entire year costs around 30 cents. That’s the price of a media monitoring workflow that would otherwise run $300+/month.
Part 4: AI Visibility Check
This is the 2026-specific part — and the one that separates a modern SEO tool from a legacy one.
43% of Google searches now end with zero clicks. When AI Mode is active, that jumps to 93%. The thing being competed for has shifted from a ranking position to a citation in an AI answer.
We’re going to check if your domain — and your competitors’ domains — are being cited in Gemini answers for your target keywords.
# ai_visibility.py
import requests
import os
from config import MY_DOMAIN, COMPETITORS, KEYWORDS

API_KEY = os.getenv("SERPENT_API_KEY")
GEMINI_URL = "https://apiserpent.com/api/ai-rank/gemini"


def check_gemini_citation(keyword, domain):
    """
    Returns citation position and cited text if domain appears
    in Gemini's answer for the keyword. None if not cited.
    """
    response = requests.get(
        GEMINI_URL,
        params={
            "q": keyword,
            "domain": domain,
        },
        headers={"X-API-Key": API_KEY},
        timeout=45,
    )
    response.raise_for_status()
    data = response.json()

    return {
        "keyword": keyword,
        "domain": domain,
        "cited": data.get("cited", False),
        "position": data.get("position"),
        "cited_text": data.get("cited_text"),
        "visibility_score": data.get("visibility_score"),
    }


def run_ai_visibility_check():
    """
    For each keyword, check if you and your competitors
    appear in Gemini answers. Surfaces your AI citation gaps.
    """
    print("🤖 Checking AI citation visibility...")
    all_domains = [MY_DOMAIN] + COMPETITORS
    results = []

    for keyword in KEYWORDS[:3]:  # limit on free tier — remove limit at Scale
        print(f"\n  Keyword: '{keyword}'")
        for domain in all_domains:
            citation = check_gemini_citation(keyword, domain)
            cited_label = f"position {citation['position']}" if citation["cited"] else "NOT CITED"
            print(f"    {domain}: {cited_label}")
            results.append(citation)

    return results
The moment you run this and see a competitor cited at position 1 in Gemini for your main keyword — while you’re not cited at all — you’ll understand why this check matters more than almost anything else in 2026 SEO.
Part 5: The Orchestrator
Wire everything together.
# main.py
import json
import os
from datetime import date
from dotenv import load_dotenv

load_dotenv()

from rank_tracker import run_rank_check
from competitor_gap import find_gaps
from news_monitor import monitor_brand_and_competitors, find_competitor_coverage_gaps
from ai_visibility import run_ai_visibility_check

def run_full_report():
    today = date.today().isoformat()
    print(f"\n{'='*50}")
    print(f"SEO Spy Report — {today}")
    print(f"{'='*50}\n")

    report = {
        "date": today,
        "rank_tracking": run_rank_check(),
        "keyword_gaps": find_gaps(),
        "ai_visibility": run_ai_visibility_check(),
    }

    news_data = monitor_brand_and_competitors()
    report["news_mentions"] = {
        domain: len(articles)
        for domain, articles in news_data.items()
    }
    report["pr_gaps"] = find_competitor_coverage_gaps(news_data)

    # Save report
    filename = f"seo_report_{today}.json"
    with open(filename, "w") as f:
        json.dump(report, f, indent=2, default=str)

    print(f"\n{'='*50}")
    print(f"Report saved: {filename}")
    print(f"{'='*50}\n")

    # Print summary
    gaps = report["keyword_gaps"]
    ai = [r for r in report["ai_visibility"] if r["domain"] == "yourdomain.com"]
    cited = sum(1 for r in ai if r["cited"])

    print(f"📊 SUMMARY")
    print(f"  Keyword gaps to close: {len(gaps)}")
    print(f"  AI citations (Gemini): {cited}/{len(ai)} keywords")
    print(f"  PR gaps (competitor mentions you missed): {len(report['pr_gaps'])}")


if __name__ == "__main__":
    run_full_report()
Run this daily with a cron job:
# Run every morning at 7am
0 7 * * * cd /path/to/seo_spy && python main.py
Or as a GitHub Action that commits the report JSON to a private repo — then you have version-controlled SEO history for free.
What Your Report Looks Like
After running the script, seo_report_2026-09-25.json contains:
{
  "date": "2026-09-25",
  "rank_tracking": [
    {"keyword": "serp api", "position": 4, "url": "https://apiserpent.com/serp-api"},
    {"keyword": "rank tracking api", "position": null, "url": null}
  ],
  "keyword_gaps": [
    {
      "keyword": "rank tracking api",
      "my_position": "not ranked",
      "competitors_ranking": {"serpapi.com": 3, "dataforseo.com": 7}
    }
  ],
  "ai_visibility": [
    {"keyword": "serp api", "domain": "apiserpent.com", "cited": true, "position": 2},
    {"keyword": "serp api", "domain": "serpapi.com", "cited": true, "position": 1}
  ],
  "news_mentions": {
    "apiserpent.com": 0,
    "serpapi.com": 3,
    "dataforseo.com": 1
  },
  "pr_gaps": [
    {
      "competitor": "serpapi.com",
      "title": "SerpApi Announces New Enterprise Tier",
      "source": "TechCrunch"
    }
  ]
}
Every field is actionable. A null rank position is a page to write. A keyword gap is a content brief. A PR gap is a pitch to draft. A missing AI citation is a third-party coverage gap.
Cost Reality Check
Let’s be real about what this costs:
| Component | Calls/month | Cost (Scale tier) |
| Rank tracking (5 keywords × daily) | 150 | $0.005 |
| Competitor gap analysis (5 keywords × daily) | 600 | $0.018 |
| News monitoring (4 queries × daily) | 120 | $0.001 |
| AI visibility (5 keywords × 4 domains × weekly) | 80 | $0.080 |
| Total | 950 | ~$0.10/month |
Ten cents a month. For a rank tracker, competitive gap analysis, news monitor, and AI citation checker.
The Scale tier is earned with a $500 one-time deposit that never expires and never downgrades. If you’re spending $100+/month on SEO tools and you code, the math is not complicated.
Where to Go From Here
This is a foundation, not a ceiling. Things worth adding:
Extend to more engines — change engine="google" to engine="bing" or engine="duckduckgo" in any call. Same code, same schema, different engine. Multi-engine rank tracking for free.
Add ChatGPT and Perplexity citation checks — Serpent API covers all four major AI engines. Swap GEMINI_URL for the Perplexity or ChatGPT rank endpoints.
Add local rank tracking — add a location parameter (city name or coordinates) and you’ve got city-by-city rank tracking for multi-location businesses.
Pipe it to a Notion database or Google Sheet — the JSON output maps cleanly to any table structure. A 20-line script turns this into a shareable dashboard.
Deploy as a weekly Slack bot — post the summary to a channel every Monday morning. Marketing teams love having SEO data without opening a tool.
The Real Point
You just built something that does what $200+/month tools do.
Not a worse version. Not a prototype. A real rank tracker with competitor gap analysis, news monitoring, and AI citation visibility — wired together in under 200 lines of Python.
The SEO tool market is pricing on brand recognition and switching costs, not on underlying technology. The underlying technology is just API calls.
You already knew how to make API calls.